JSON vs XML vs Protocol Buffers: Size, Speed and Trade-offs
How text and binary serialization formats differ, what really drives payload size and parse time, and how to benchmark formats honestly for your own data.
· Updated · 9 min read
Every time two systems exchange data, someone has chosen a serialization format. Most of the time it is JSON, because it is the default for web APIs. Sometimes it is XML because a partner or standard requires it. And increasingly, for service-to-service traffic, it is Protocol Buffers via gRPC.
This guide compares the three on size, speed, schema support and tooling, explains where the differences come from, and covers how to benchmark formats honestly. The Data Format Comparison tool lets you see JSON and XML side by side for your own data.
A short history
XML became a W3C Recommendation in 1998, derived from SGML. It powered SOAP web services, RSS and Atom feeds, Office document formats (DOCX and XLSX are zipped XML), SVG, Android layouts and countless enterprise integrations. Its ecosystem includes XML Schema (XSD) for validation, XPath for querying and XSLT for transformation.
JSON was described by Douglas Crockford in the early 2000s and took over web APIs during the move to AJAX and REST. It maps directly onto the objects and arrays of JavaScript and most other languages, which made it far simpler to work with than XML for typical API payloads.
Protocol Buffers were developed at Google, where they had long been used internally, and were open-sourced in 2008. They are a binary format defined by a schema in a .proto file, and they are the default payload format for gRPC, released in 2016.
The same record in each format
{"id": 42, "name": "Ada", "active": true}
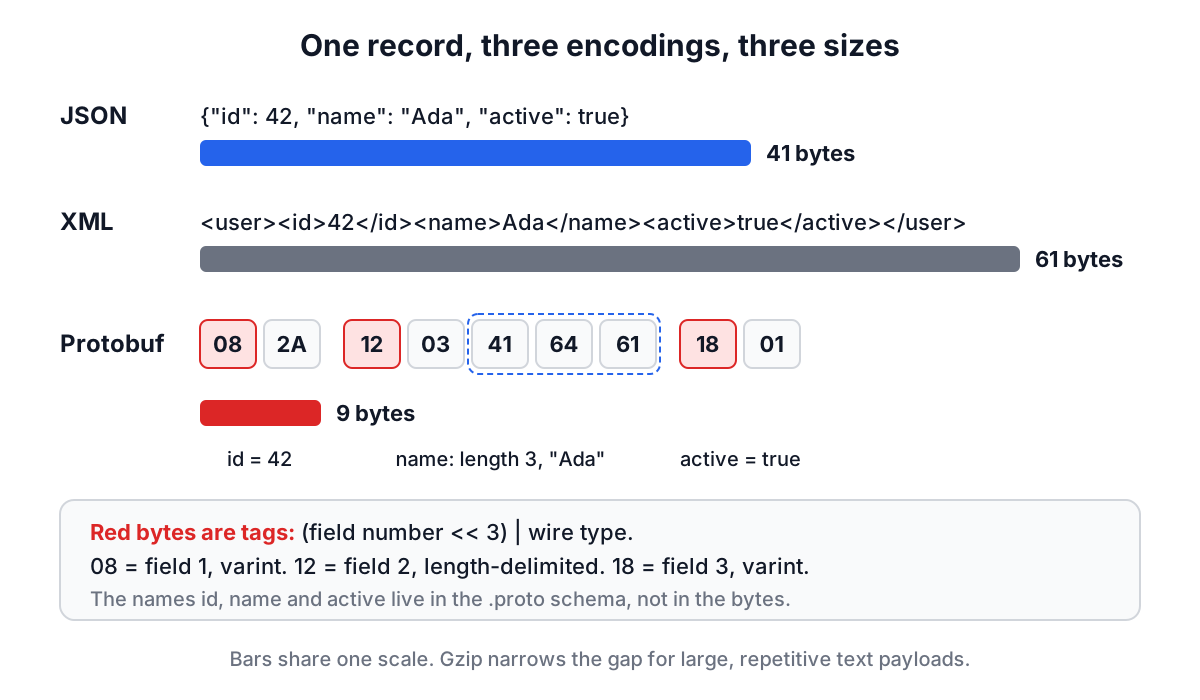
<user><id>42</id><name>Ada</name><active>true</active></user>
message User {
  int32 id = 1;
  string name = 2;
  bool active = 3;
}
The protobuf message on the wire is roughly 9 bytes: a one-byte tag and a one-byte value for id, a tag, a length byte and 3 bytes for name, and a tag and a byte for active. The JSON is 41 bytes and the XML 61.
Where the size differences come from
- XML repeats every element name twice, opening and closing. Attributes and namespaces add more.
- JSON repeats every key once per object. In an array of 10,000 objects, the key names are written 10,000 times.
- Protobuf replaces names with small numeric field tags defined in the schema, and encodes integers as variable-length "varints", so small numbers take one byte. Default values are often omitted entirely.
The more repetitive the structure, the bigger the gap. For a single small object, the difference rarely matters. For millions of messages per second between services, it adds up to real bandwidth and CPU.
Compression narrows the gap
Text formats compress very well precisely because they are repetitive. Gzip or Brotli on an HTTP response often shrinks JSON by 70 to 90%. After compression, the size difference between JSON and protobuf is much smaller than the raw numbers suggest, though protobuf usually still wins, and it avoids spending CPU on compression in the first place.
Speed
Parsing text means scanning characters, handling escapes and converting digit strings into numbers. Parsing protobuf means reading tags and lengths and copying bytes, guided by generated code that already knows the schema. Protobuf is typically faster to serialize and parse, sometimes by a wide margin.
Two caveats:
- JSON parsers are very fast now. Engines like V8 have heavily optimized
JSON.parse, and libraries such as simdjson parse gigabytes per second using SIMD instructions. For many workloads JSON parsing is not the bottleneck. - XML parsing is usually the slowest, especially with DOM parsers that build a full tree in memory. Streaming parsers (SAX, StAX) help with large documents.
Schemas and evolution
| JSON | XML | Protobuf | |
|---|---|---|---|
| Human-readable | Yes | Yes | No (binary) |
| Schema | Optional (JSON Schema) | Optional (XSD, DTD) | Required (.proto) |
| Comments in data | No | Yes | No |
| Code generation | Optional | Optional | Standard |
| Adding fields safely | By convention | By convention | Built in, via field numbers |
| Browser support | Native | Native (DOMParser) | Needs a library |
| Debugging with curl | Easy | Easy | Needs tooling |
Protobuf's schema is both its strength and its cost. Field numbers make it straightforward to add new fields without breaking old clients, which is valuable in large systems. The rules are strict, though: never reuse a field number, and never change a field's type. And you cannot read a protobuf payload in a terminal without the schema and a tool like protoc --decode or grpcurl.
Benchmarking honestly
If performance matters enough to choose a format based on it, measure with your own data. Common mistakes:
- Tiny samples. One small object tells you nothing about throughput.
- A single run. JIT compilers need warm-up, and garbage collection adds noise. Run many iterations and look at medians and high percentiles, not just the average.
- Ignoring compression. Compare what actually crosses the network.
- Ignoring the rest of the request. If a request spends 200 ms in the database, saving 1 ms of parsing does not matter.
- Comparing different data. Make sure each format encodes exactly the same information.
About the RedBison comparison tool
The tool really serializes your data to JSON and XML in the browser and measures their size and timing, which makes the structural overhead of XML easy to see. The Protocol Buffers column now uses real protobufjs encoding and decoding with a generic JSON-value schema, preserving arbitrary custom data rather than discarding fields not covered by a fixed User schema. Its size is the actual encoded byte count. Each format runs the selected number of measured iterations, after one warm-up run, and timings use the selected average or interpolated percentile. XML parsing uses the browser DOMParser. These results compare specific implementations: a generic JSON-value protobuf schema can be larger than an optimized application schema, and DOM construction is different work from constructing JSON objects. Benchmark your production schema before making a decision.
Choosing a format
- Public web APIs: JSON. Universal support, easy debugging, and every client can consume it.
- Internal service-to-service calls at scale: Protobuf with gRPC, if you can adopt the tooling. Strong contracts and efficient payloads.
- Document-centric data, industry standards or existing integrations: XML, where its schemas, namespaces and mixed content are genuinely useful or required.
- Other options worth knowing: MessagePack and CBOR (binary JSON-like formats without a required schema), Avro (schema-based, popular with Kafka), and FlatBuffers or Cap'n Proto (zero-copy access for very low latency).
In my experience, interoperability and team familiarity matter more than raw speed for most systems. Start with JSON, measure, and move hot paths to a binary format when the numbers justify it.
Related tools
- JSON Formatter to inspect JSON payloads
- Protocol Buffers Tools to work with protobuf schemas
- Avro Tools for Apache Avro data
Frequently asked questions
How much smaller is Protocol Buffers than JSON?
For a small record with an id, a name and a boolean, Protocol Buffers takes roughly 9 bytes on the wire, against 41 bytes of JSON and 61 bytes of XML. Protobuf replaces field names with small numeric tags and encodes small integers as one-byte varints, while JSON repeats every key in every object and XML repeats each element name twice.
How does Protocol Buffers handle schema changes?
Protocol Buffers uses field numbers defined in a .proto schema, which makes it straightforward to add new fields without breaking old clients. The rules are strict: never reuse a field number and never change a field's type. The cost is that a protobuf payload cannot be read in a terminal without the schema and a tool such as protoc --decode or grpcurl.
Should I use JSON or Protocol Buffers for an API?
Use JSON for public web APIs, because every client can consume it and it is easy to debug. Use Protocol Buffers with gRPC for internal service-to-service calls at scale, if you can adopt the tooling, for strong contracts and efficient payloads. A sensible approach is to start with JSON, measure, and move hot paths to a binary format when the numbers justify it.
How do I benchmark serialization formats fairly?
Benchmark serialization formats with your own realistic data rather than one tiny object, run many iterations after warm-up, and look at medians and high percentiles, not just averages. Compare compressed sizes, since that is what crosses the network, make sure each format encodes exactly the same information, and check whether parsing even matters next to database time.
What are the alternatives to JSON, XML and Protocol Buffers?
Alternatives to JSON, XML and Protocol Buffers include MessagePack and CBOR, which are binary JSON-like formats without a required schema; Avro, which is schema-based and popular with Kafka; and FlatBuffers and Cap'n Proto, which offer zero-copy access for very low latency.
Sources and further reading
- Extensible Markup Language (XML) 1.0 (Fifth Edition), W3C. The XML Recommendation, first published in 1998.
- RFC 8259: The JavaScript Object Notation (JSON) Data Interchange Format, IETF.
- Introducing JSON, Douglas Crockford. The format's original description and grammar.
- Protocol Buffers: Overview, Google. What protobuf is and how .proto schemas evolve.
- Protocol Buffers: Encoding, Google. How field numbers and varints keep protobuf messages small.
- Introduction to gRPC, gRPC Authors. Protocol Buffers as gRPC's default message format.
Open the Data Format Comparison
More Data Formats
Every tool in the Data Formats section, free and in your browser.